
Extract structured content from HTML with predictable accuracy
Submit HTML. Detect headings and paragraphs. Get consistent, order-preserving output for your test suites and content pipelines.
How it works
Three steps from raw HTML to validated, structured text.
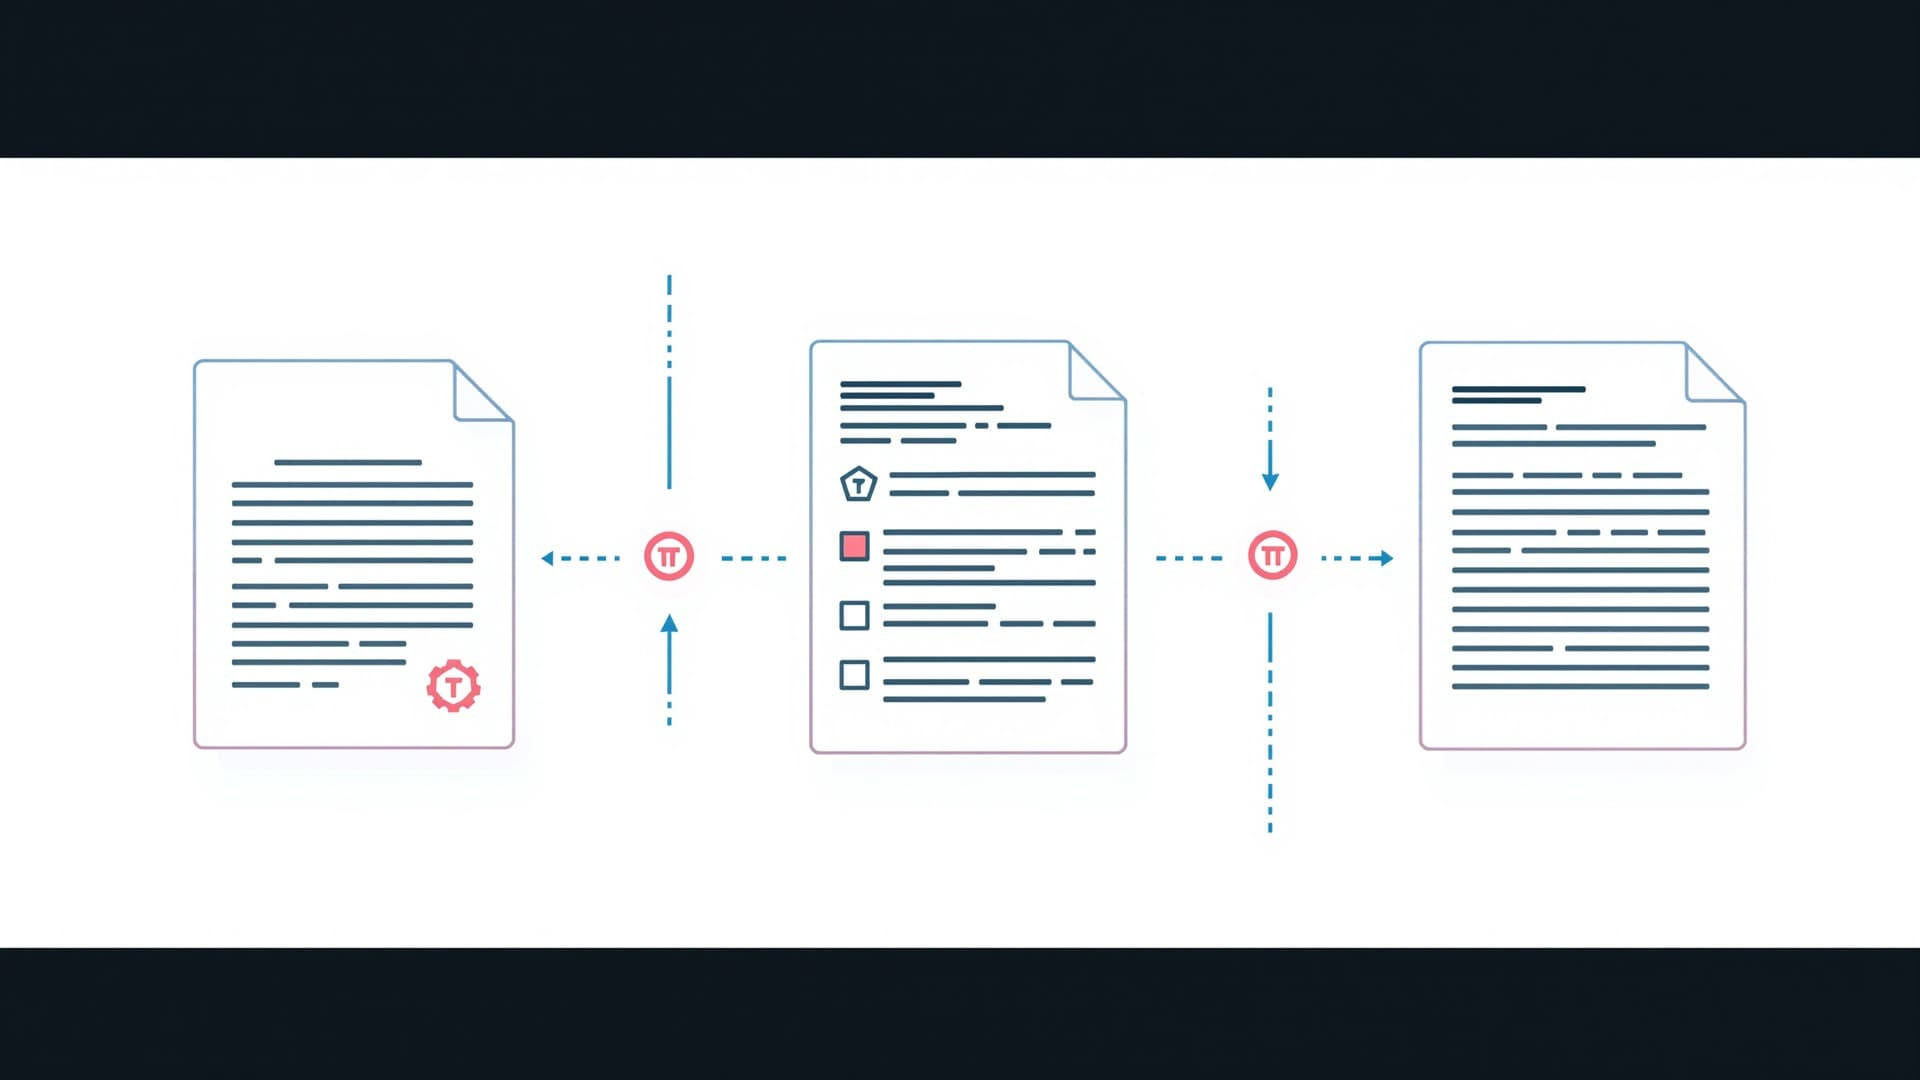
Submit HTML
Provide a web page URL or paste raw HTML. The extractor accepts any valid document structure.
Detect elements
Headings and paragraphs are identified and tagged by type while preserving their source order.
Get structured output
Receive predictable, consistently formatted text you can compare, validate, or feed into your pipeline.
Why ParseOrder Labs
Reliable extraction you can build tests against.
Structure-preserving extraction
Headings and paragraphs retain their original order and hierarchy. Compare output against source markup without guesswork.
Predictable output
Every run returns consistently structured text — same input, same result. Your tests pass or fail on the content, not the format.
Test-oriented workflow
Built for developer suites and CI pipelines. Submit, extract, compare, retry — all through a clean API designed for automation.
Predictable pricing for predictable output
Start free. Scale with your test suite.
Sandbox
Evaluate the API. No card required.
- ✓1,000 requests/month
- ✓Community support
- ✓Full API access
Developer
For solo builders and small teams in production.
- ✓25,000 requests/month
- ✓API keys
- ✓Basic usage logs
- ✓$0.60 per 1k overage
Team
Engineering teams running production validation.
- ✓250,000 requests/month
- ✓Shared workspaces
- ✓Retention controls
- ✓Up to 5 seats included
- ✓$0.60 per 1k overage
Frequently asked questions
Which HTML elements does ParseOrder Labs detect?
The initial extraction scope covers headings (h1–h6) and paragraph text. Detected elements are returned in source order with their type clearly labelled.
How is source order preserved?
The extractor walks the document tree in DOM order, so headings and paragraphs appear in the output exactly as they appear in the markup. No re-sorting, no omission.
What does the structured output look like?
Each extraction run returns a consistent JSON response with element type, text content, and sequence index. The format stays identical across runs so your diff-based tests are reliable.
Can I use it inside CI or automated test suites?
Yes. The API is designed for automation: submit HTML, receive structured output, compare against expected results. Most teams call it from their existing test harness.
What happens if I exceed my plan's request limit?
Additional requests are billed at $0.60 per 1,000. You can monitor usage through your API dashboard. No service interruption — overage is metered and invoiced.
See what your parser is really returning
Submit HTML and inspect the structured output in minutes. No credit card required for the Sandbox plan.